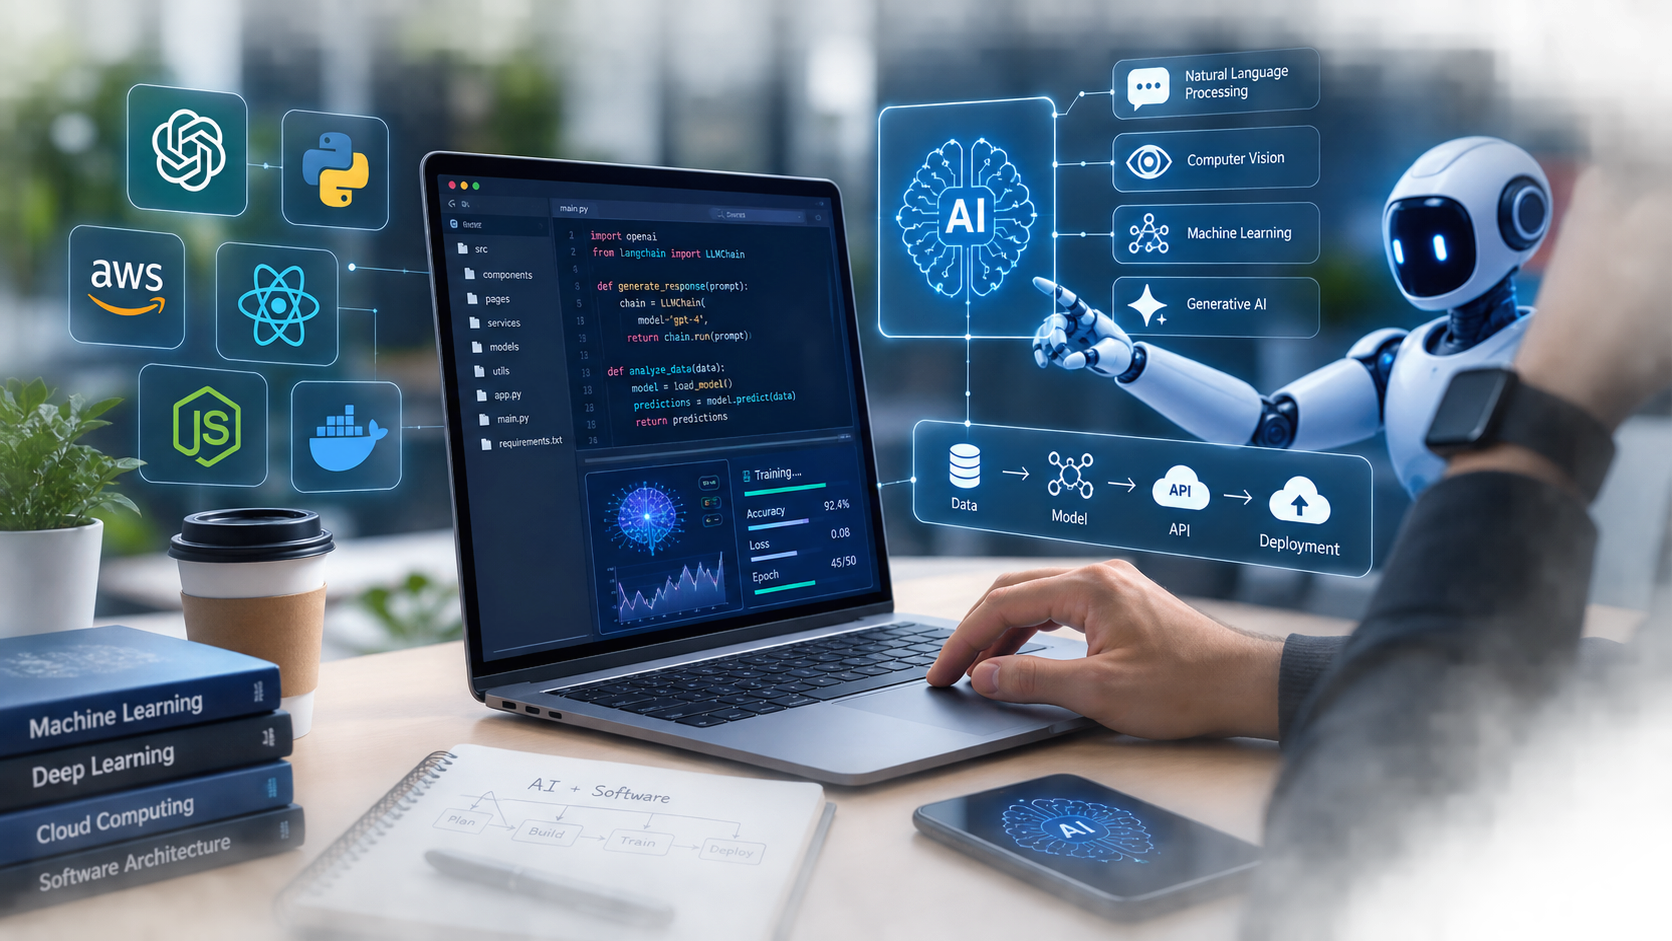
Optimizing LLM Inference: Quantization, Caching & Cost Reduction
 AI & Machine Learning
 10 min read
 4200 Views
Techniques for shrinking AI inference latency and server GPU expenditures using semantic prompt caching.
Share


Previous
Building Resilient Real-Time Systems with WebSockets & Redis
Next
Micro-Frontends at Enterprise Scale: Module Federation in Action

3Replies to “Optimizing LLM Inference: Quantization, Caching & Cost Reduction”
R
by Rashmi
3 hr ago
The right tech stack can make a huge difference in your SaaS product's performance, scalability, and long-term success.
T
by Tanisha
3 hr ago
Choosing the right technologies early helps build a secure, flexible, and high-performing SaaS product that can grow smoothly.
R
by Rashmi
3 hr ago
A well-structured tech stack also makes hiring and onboarding developers much easier as the company scales.
Leave a Reply
Your email address will not be published. Required fields are marked *